
AI Physics
Overview
The Rescale AI PhysicsAlso referred to as Physics-Informed Machine Learning or Phy... More Operating System (OS) provides a guided, end-to-end way to turn simulationSimulation is experimentation, testing scenarios, and making... More data into high-accuracy surrogate models with fast and flexible inference. It is designed for simulation engineers — not AI experts — and supports a range of production-ready modelA numerical, symbolic, or logical representation of a system... More architectures across multiple solvers.
A surrogate model is a fast approximation of a simulation solverA solver is a numerical algorithm or a software tool that so... More, trained on completed simulation results. Once trained, a surrogate model can predict outputs for new inputs in seconds instead of hours, allowing you to explore more design candidates without running additional solver jobs.
Benefits
- End-to-end guided workflow — The Rescale AI Physics OS manages the full lifecycle from simulation data preparation through model training, validationValidation is the act of ensuring that a product, system, or... More, and inference, with no custom scripts or machine learning pipelines required.
- Designed for simulation engineers — built-in Jupyter Notebook templates, an AI copilot, and default training parameters make it accessible without deep AI expertise.
- Fast inference, multiple environments — run inference interactively in AI Physics Training and AI Physics Inference, locally on any workstationA workstation is a powerful computer system designed for pro... More or laptop via the local inference runner and client, or natively inside Blender and Autodesk Alias.
- Broad solver support — AI Physics supports steady-state CFD and static FEA workflows today, with support for additional solvers and analysis types expanding over time.
The AI Physics Workflow
The end-to-end process has four stages:
- Prepare Rescale Jobs — run your simulation jobs on Rescale with data preparation Automations enabled
- Create an AI Dataset — build a structured dataset from your completed simulation jobs
- Train the Surrogate Model — use AI Physics Training to select a model architecture, train, and validate
- Run Inference — use the trained model to predict outputs for new inputs and geometries instantly
Prerequisites
Before you begin:
- AI Physics must be enabled for your organization. If you don’t see AI Datasets, Model Builder, or AI Models in the Rescale side navigation, contact your Rescale representative

- To be able to create AI Datasets and AI Models in the Rescale platform, you need to first create an API key from your User Profile Settings
Prepare Rescale Jobs
Before training a surrogate model, you need simulation data that covers the input space you want the model to predict over. The quality and coverage of your training data directly determines how well the surrogate model generalizes.
Run a parameter sweep or design of experiments (DOE)DOE stands for "Design of Experiments." It is a statistical ... More that samples a representative range of your inputs. Each completed run becomes one training sample or dataset case.
When setting up your Rescale jobs, enable two types of data preparation Automations so that your results are ready for AI training:
- MetadataMetadata is data that provides information about other data,... More Extraction — extracts global input variable names and values from your solver files, and stores them as Custom Fields on each job. These become the global variables for your surrogate model.
- AI Extraction — converts your solver output files to a standardized PyVista compatible format that AI Physics Training can ingest.
Tip: Contact your Rescale representative if you do not see Automations for your solver of interest.
To add Automations to a job:
- From the Rescale platform, open or create a job.
- Navigate to the Automations tab in the job configuration.
- Under the available Automations, locate and enable the Metadata Extraction Automation for your solver.
- Enable the AI Extraction Automation for your solver.
- Submit and run your jobs as usual.
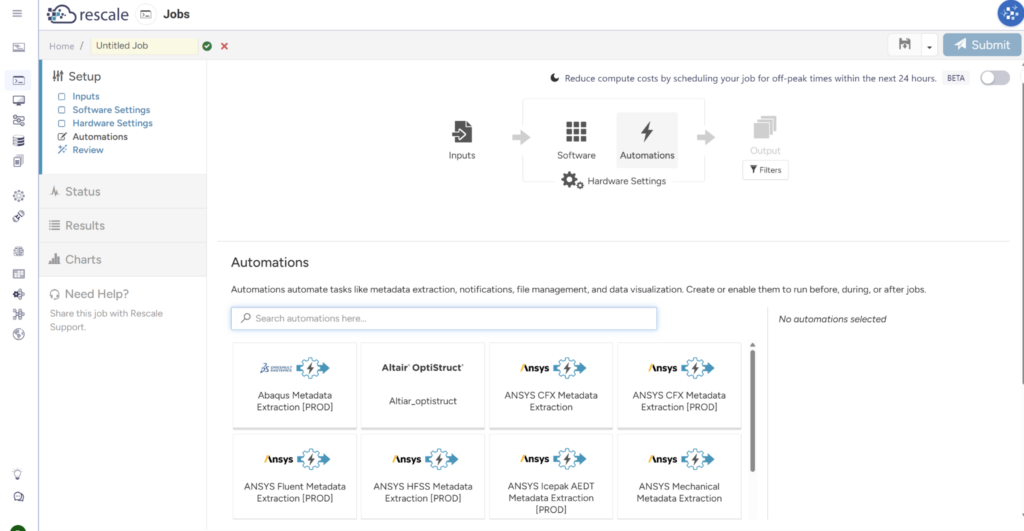
Once your DOE is complete, verify that each run has finished successfully and that the expected output files and Custom Fields are present before proceeding.
How many jobs do I need? For problems with a small number of inputs and smooth, continuous outputs, a few dozen samples may be sufficient. High-dimensional inputs or highly non-linear responses typically require hundreds of samples. Start with what you have and expand if model accuracy is insufficient.
Create an AI Dataset
Once your simulation jobs are complete, you create an AI Dataset — a structured collection of simulation results that the surrogate model will be trained on.
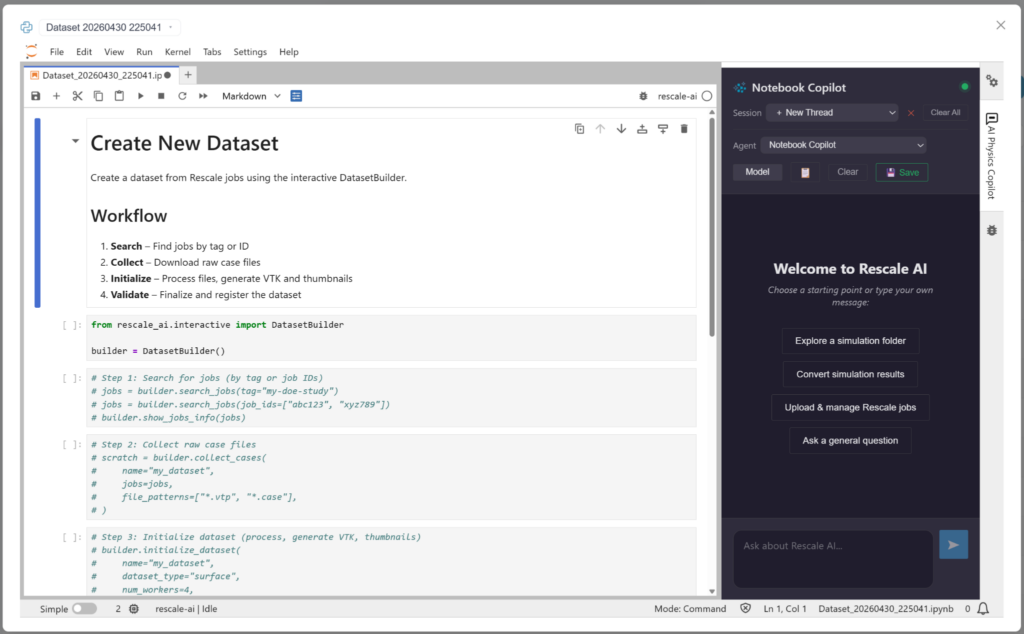
AI Dataset creation happens inside a Training Session using a Jupyter Notebook template. The template guides you through collecting your job results, organizing them into the dataset structure, and validating that inputs and outputs are consistent across all runs.
To create an AI Dataset:
- From the Rescale platform, navigate to Model Builder in the left sidebar and click New Training Session.
- Click Continue without selecting a Dataset or Model.
- Click New Storage Device to create and configure a storage device to hold your dataset and model files and click Continue.
- Add a Workstation and configure the workstation hardware. Click Create to create the Training Session and launch the workstation.
- Once the Training Session is ready, click Open Session, then click Open App to launch AI Physics Training.
- From AI Physics Training, click New Dataset. This opens a Jupyter Notebook template with step-by-step instructions for loading your completed Rescale job results and building the dataset.
- Follow the notebook instructions. The notebook will walk you through running commands to collect cases, initialize the dataset, and validate it. Once validation passes, your new AI Dataset appears in the AI Datasets table in Rescale.
- From AI Physics Training, you can merge, split, duplicate, and delete AI Datasets. You can also review the dataset cases and inspect the input and output variables.
Mesh decimation: For high-resolution meshes, you can perform mesh decimation in AI Physics Training to reduce the mesh size and shorten training time. This is optional but can significantly speed up training for datasets with large meshes.
Tip: If you’re new to AI Physics, follow the end-to-end tutorials listed in the Tutorials section below before setting up your own jobs. The tutorials use pre-prepared job results so you can practice dataset creation and model training without running a full DOE first.
Notebook Copilot: The Notebook Copilot uses the Qwen2.5-Coder-14B large language model from Alibaba, licensed under Apache 2.0. No data is sent from the Notebook Copilot to Alibaba or third parties.
Train the Surrogate Model
Overview
Once your AI Dataset is prepared, you can train a surrogate model that learns the relationship between your simulation inputs and outputs. AI Physics offers two configuration methods: Auto Tune (recommended) for automated hyperparameter optimizationOptimization is a systematic method to determine the values ... More, and Manual for full control over every training parameter.
Highlights
- Auto Tune (Recommended): Automatically explore multiple hyperparameter configurations in parallel, drops weak candidates, and keeps the best model — work that would take weeks of manual experimentation
- Four production-ready architectures: DoMINO, GeoTransolver, MeshGraphNet (built on PhysicsNeMo and licensed under Apache 2.0 and PyTorch) and TwoStreamTransformer (Rescale developed)
- Built-in evaluation dashboards: R² scores, residual distributions, and 3D error visualizations to validate model quality
Create a New Model
- Navigate to AI Physics > Models.
- Click + New Model.
- Select the AI Dataset you created and review the input and output parameters. Confirm that the correct variables are included.
- Choose how to split your data: you can automatically split into training and test sets, or use separate dedicated datasets for each.
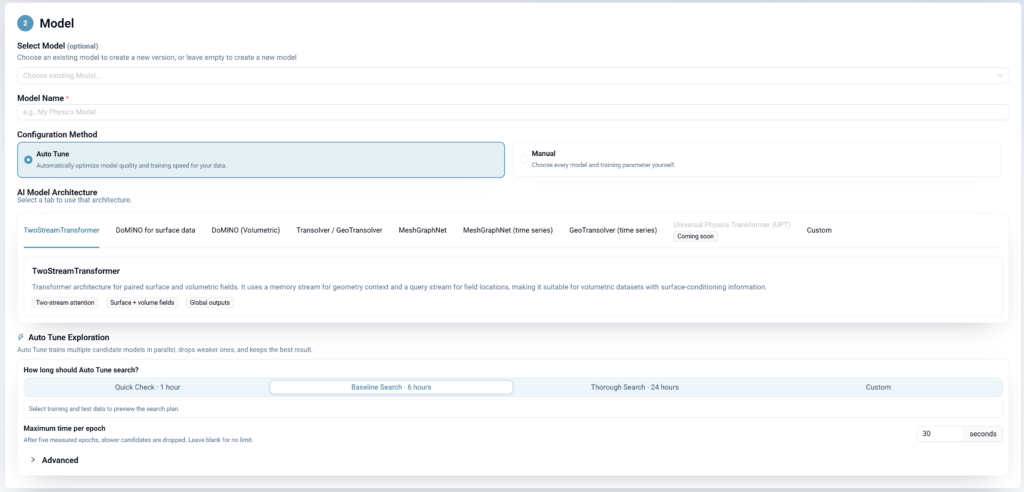
- Enter a Model Name (e.g., “My Physics Model”).
- Optionally, select an existing model from the Select Model dropdown to create a new version of a previously trained model.
Choose a Configuration Method
Select Auto Tune or Manual under Configuration Method.
| Use Auto Tune when… | Use Manual when… |
|---|---|
| You want the best model without tuning expertise | You have specific hyperparameter constraints |
| You’re training on a new dataset for the first time | You need full control over every training parameter |
| You want to explore multiple configurations efficiently | You’re reproducing a prior experiment exactly |
Auto Tune
Auto Tune automatically optimizes your surrogate model’s hyperparameters and training configuration. You choose how long to search and Auto Tune handles the rest.
Select Your Model Architecture
Choose the architecture that matches your data type. Each tab displays a description and tags indicating supported use cases.
| Architecture | Best for |
|---|---|
| TwoStreamTransformer | Highly efficient and suitable for both CFD and FEA use cases |
| DoMINO | Steady-state CFD surface variable prediction (e.g., surface pressure, wall shear stress, drag and lift coefficients) |
| Transolver / GeoTransolver | A geometry-aware transformer architecture designed for predictions over complex 3D geometries on unstructured meshes, where accurately capturing geometric relationships between mesh points is important. |
| MeshGraphNet | A graph neural network architecture well-suited for FEA problems with complex deformation and stress field predictions |
Set Search Duration
Auto Tune needs a time budget to explore configurations. Longer searches try more candidates and are more likely to find an optimal model.
| Option | Duration | Best for |
|---|---|---|
| Quick Check | 1 hour | Verifying your data pipelineA system or workflow that automates the movement and transfo... More works, getting a rough baseline |
| Baseline Search (Recommended) | 6 hours | Most use cases — good balance of exploration and cost |
| Thorough Search | 24 hours | Large or complex datasets where marginal accuracy gains matter |
| Custom | Set your own | When you know your compute budget or have specific time constraints |
Note: Search time covers exploration and model selection only. Initial setup and final model polish happen afterward and do not count against this time.
Cost estimation: Your maximum Auto Tune cost is bounded by: search duration × hardware hourly rate.
Maximum time per epoch: If you want to specify a maximum runtime for each epoch you can use this setting. The default should be sufficient for most cases.
Advanced Settings (Optional)
Expand the Advanced: Population Initialization section to configure how Auto Tune initializes its search.
Candidate Initialization
Controls where Auto Tune gets its starting hyperparameters:
- Fresh population (default) — Every candidate starts from scratch with random hyperparameters. Use this for your first model on a dataset.
- Compatible prior runs — Seeds hyperparameters from compatible prior Auto Tune runs in your organization, while keeping model weights fresh. Use this when your team has trained similar models before and you want to benefit from that history. The current run’s best hyperparameters are contributed back to the registry for future use.
Note: Compatible prior runs borrows the configuration recipe (learning rate, batch size, architecture settings) from prior experiments. It does not transfer trained model weights.
Optional Hyperparameter Seed
If you have a completed model of the same architecture trained on this dataset, you can use its hyperparameters as a starting point. This narrows the search space and can lead to faster convergence.
This option is only available when a compatible completed model exists. If you see “No compatible base models,” no prior model of the selected architecture has been trained to completion on your current dataset.
Select Hardware
Choose a GPU configuration for training. Both Auto Tune and Manual modes use this hardware selection.
- Single GPU: lower cost, suitable for smaller datasets and models.
- Multi-GPU: accelerates training with data-parallelism. Use when your model or batch size exceeds single-GPU memory. It does not fix GPU CUDA Out of Memory errors; for those you need a card with more memory per GPU.
Available hardware options display GPU type, VRAM, vCPU, RAM, and hourly cost.

Review and Launch
The Auto Tune Preflight panel validates that all required inputs are configured before you can launch:
- Training dataset selected
- Model name entered
- GPU hardware selected
- Search plan configured (dataset setup complete)
Resolve any items marked Needs Attention, then click Start Auto Tune.

Monitor Training Progress
Auto Tune Evolution
Once launched, navigate to the Auto Tune Evolution tab to track progress in real time.
Key Metrics
| Metric | What it means |
|---|---|
| Models Tried | Candidates explored so far (out of planned total) |
| Models Advanced | Candidates promoted to full-length training |
| Best Accuracy So Far | Current best validation accuracy across all candidates |
| GPU Memory | Memory consumed (of total available on selected hardware) |
| Search Progress | Time elapsed and remaining in your search budget |
How Auto Tune Works (3 Phases)
- Explore & Narrow Down. Quick training runs evaluate many configurations. Weak candidates are dropped early to save compute.
- Train Top Models Fully. Surviving candidates receive full-length training to reach their true potential.
- Evaluate Winner. Final accuracy test on held-out data selects the best model.
Leaderboard
The Leaderboard — Best Models So Far ranks candidates by validation accuracy. Status shows whether a model advanced (promoted to deeper training), was dropped, or is still training.

Technical Details (Power Users)
Expand Show technical details for deeper insight:
- Efficiency Frontier — Plots validation objective vs training cost (seconds per epoch). Identifies models that are both accurate and efficient.
- Promotion Ladder — Visualizes the rung system. Candidates must prove themselves at progressively longer epoch counts (e.g., Rung 1: 100 epochs → Rung 2: 200 epochs → Rung 3: 300 epochs) to advance.

Training Curves
The Training Curves tab shows training and validation loss over time for the selected model version.
Evaluate Results
Understanding Accuracy vs R²
You’ll see two different metrics during and after training. They measure different things:
| Metric | Where you see it | What it measures |
|---|---|---|
| Accuracy (%) | Auto Tune leaderboard during search | Internal search metric used to rank and promote candidates. Measures how well a candidate performs relative to others during exploration. |
| R² (Performance) | Versions table after completion | Final evaluation on held-out test data. The definitive quality metric for your model. Measures how well predictions match true values on data the model never trained on. |
These metrics can tell different stories. A candidate with high leaderboard accuracy during search may produce a lower R² on final evaluation because held-out test data presents harder cases than the training split. Always use R² as your ground truth for model quality.
Interpreting R²
| R² value | Interpretation | Action |
|---|---|---|
| Close to 1.0 | Strong model — predictions closely match true values | Deploy for inference |
| Close to 0 | Model is no better than predicting the average | Increase search duration or add more training data |
| Negative | Model performs worse than predicting the average | Try a longer search, more data, or a different architecture |
Important: Auto Tune completing successfully does not guarantee a high-quality model. Always check the R² score in the Versions table before deploying.
Model Version Details
The winning candidate is automatically promoted to a model version, visible in the Versions table:
| Field | Description |
|---|---|
| Version Name | Model name and version identifier |
| Architecture | The architecture used (e.g., TwoStreamTransformer) |
| Performance | R² score on held-out test data |
| Training Time | Wall-clock time for the final model training (not the full search duration) |
| Lineage | “From Scratch” or the seed source used |
| Status | Completed, Failed, or In Progress |

Manual Configuration
Select Manual when you need full control over every training parameter.
In Manual mode, you configure:
- Model architecture: same four options as Auto Tune (TwoStreamTransformer, DoMINO, Transolver/GeoTransolver, MeshGraphNet)
- Hyperparameters: learning rate, batch size, number of epochs, optimizer settings, and architecture-specific parameters
- Hardware: same GPU selection as Auto Tune
Default parameters are suitable for most use cases. Adjust individual parameters only if you have specific requirements or are iterating on a prior experiment.

Fine-Tuning an Existing Model
To improve a previously trained model:
- Select the existing model from the Select Model dropdown when creating a new model.
- The new version inherits the prior model’s architecture and configuration as a starting point.
- With Auto Tune, use the Optional Hyperparameter Seed in Advanced settings to seed from the prior model’s hyperparameters.
- With Manual, adjust specific parameters and retrain.
This is useful when you’ve added new simulation data to your dataset or want to improve accuracy on specific regions of the design space.
Troubleshooting
Auto Tune Failed
If you see “Auto Tune did not complete any valid trials,” the search budget was likely too short for your data complexity:
- “Measured epoch cost leaves room for fewer than three additional search trials” — Your data/architecture combination is expensive per epoch. Increase your search budget (try Baseline Search or Thorough Search) to allow broader exploration.
- Verify that your training dataset is correctly formatted and accessible.
- Try a different architecture if the failure persists.
Low R² After Completion
If your model completes but shows a low or negative R²:
- Increase search duration. A Quick Check may not explore enough candidates for complex datasets.
- Add more training data. More simulation samples improve generalization.
- Try a different architecture. Some architectures perform better on certain data types.
- Check data quality. Ensure your simulation outputs don’t contain errors or extreme outliers.
GPU Out of Memory
If training fails due to GPU memory:
- Select hardware with more VRAM (check the GPU Memory metric during training).
- Note that switching to Multi-GPU does not fix CUDA Out of Memory errors — you need a card with more memory per GPU.
Run Inference on the Surrogate Model
Once a model is trained, you can run inference to predict simulation outputs for new input configurations — without launching a solver. AI Physics offers several inference options depending on your workflow and environment.
| Option | Best for |
|---|---|
| AI Physics Training | Quick interactive exploration while actively developing a model |
| AI Physics Inference | Dedicated inference sessions on AI Models, without requiring a storage device |
| Local inference runner and client | Running inference on a local workstation or laptop, including offline and on-premises environments |
| CADCAD stands for Computer-Aided Design. It is the use of compu... More plug-ins (Blender, Autodesk Alias) | Running inference natively inside your CAD tool |
Run Inference in AI Physics Training
You can run inference directly in AI Physics Training while reviewing a trained model. This is the quickest way to explore model predictions during model development.
- In AI Physics Training, navigate to the Inference tab
- In the Model panel, click Change to select the Model you would like to run inference on
- Configure the global input variables you want to vary using the input controls.
- Click Run Inference to generate a prediction. Results are displayed as an interactive 3D visualizationVisualization is the representation of complex scientific or... More and you can change the output displayed.
- Adjust inputs and re-run to explore how outputs change across your design space.

Run Inference in AI Physics Inference
AI Physics Inference is a dedicated inference environment that does not require a storage device to run inference on your AI Models.
- From the AI Models page in Rescale, click Run Inference.
- In the create workstation page, select the workstation hardware to run AI Physics Inference and click Submit.
- Once the workstation is launched, select Open App from the workstation status page.
- Running inference is the same as with AI Physics Training.
Run Inference Locally
The local inference runner and client let you download trained models from Rescale and run inference on any workstation or laptop — including offline and on-premises environments. The rescale-ai-client Python package provides access to the local inference runner and a standard API for building custom interfaces.
Note: For access to the local inference runner and client, contact your Rescale representative.
Run Inference in CAD Tools
Rescale provides inference plug-ins for Blender and Autodesk Alias so designers can run surrogate model predictions natively within their CAD environment.
- To run inference on a given Model with Blender, navigate to Models from AI Physics Training or AI Physics Inference.
- Navigate to the Model and version that you want to run inference on and click Run Inference in Blender. This launches Blender with the Model loaded and the Rescale AI Physics plug-in installed.
- Adjust global inputs and geometry directly in the Blender environment, then run inference to see predicted outputs overlaid on your geometry in near real time.

Note: Surrogate predictions are most reliable within the range of inputs covered by your training data. Extrapolating beyond that range will produce less accurate results. It is good practice to validate a sample of predictions against full solver results before using the model for critical decisions.
Note: For access to the Autodesk Alias inference plug-in, contact your Rescale representative.
Tutorials
Follow the tutorials below to train your first surrogate model end-to-end. Each tutorial uses pre-prepared job results so you can walk through the full AI Physics workflow — dataset creation, model training, and inference — without setting up your own DOE first.
- OpenFOAM AI Physics Tutorial — train a steady-state CFD surrogate model using OpenFOAM results
- CalculiX AI Physics Tutorial — train a static FEA surrogate model using CalculiX results
- OpenRadioss AI Physics Tutorial — train a transient FEA (crash) surrogate model using OpenRadioss results
FAQs
What is a surrogate model, and why would I use one? A surrogate model is trained on completed simulation results. Once trained, it can predict outputs for new inputs in seconds rather than hours. Surrogate models are useful for design space exploration, sensitivity analysis, and optimization studies where running a full solver for every configuration would be too expensive or slow.
Do I need AI or machine learning experience to use AI Physics? No. AI Physics is designed for simulation engineers. The Jupyter Notebook templates, default model parameters, and built-in evaluation dashboards guide you through each step. An AI copilot is also available in the notebook interface to help answer questions and suggest next steps using natural language.
How do I know if my trained model is accurate enough to use? After training, review the evaluation dashboards in AI Physics Training. These show R² scores broken down by output variable, residual distributions, and 3D error visualizations across your test cases. A high R² and low residuals across your test set indicate the model generalizes well. Always validate a sample of predictions against full solver runs before using the model for critical decisions.
Can I retrain or fine-tune a model after the initial training run? Yes. In AI Physics Training, go to Models > Training Approach and select Fine-tune Existing to resume training from a previous checkpoint. This is useful when you want to improve accuracy without starting from scratch, or when you have new training data to add.
What if I’m using a solver that isn’t listed as supported? AI Physics requires Metadata Extraction and AI Extraction Automations to be available for your solver. If your solver is not yet supported, contact your Rescale representative. Solver support is expanding over time, and your use case may inform the roadmap.