
AI Physics Auto Tune for Faster, Better Surrogate Model Training
Introducing Auto Tune for AI Physics
Training a high-accuracy surrogate model used to mean manually creating models one at a time, tweaking hyperparameters, and comparing results — a process that could take weeks. Auto Tune changes that: you set a time budget, and Auto Tune automatically explores multiple hyperparameter configurations in parallel, drops weak candidates early, and delivers the best model. It works with all four production-ready architectures (DoMINO, TwoStreamTransformer, GeoTransolver, and MeshGraphNet) and is designed for simulation engineers — no machine learning expertise required.
Release Highlights
What is it?
Auto Tune is an automated hyperparameter optimization system for AI Physics surrogate models. When you create a new model, select Auto Tune as your configuration method, choose a search duration, and click Start Auto Tune. The system handles learning rates, batch sizes, architecture parameters, and optimizer settings automatically.
Auto Tune runs in three phases:
- Explore & Narrow Down — Quick training runs evaluate many configurations. Weak candidates are dropped early to save compute.
- Train Top Models Fully — Surviving candidates receive full-length training to reach their true potential.
- Evaluate Winner — Final accuracy test on held-out data selects the best model.
You monitor progress in real time on the Auto Tune Evolution tab, which shows models tried, models advanced, current best accuracy, GPU memory usage, and search progress. A Leaderboard ranks candidates by validation accuracy so you can see which models advanced, which were dropped, and which are still training.
Search duration options:
| Option | Duration | Best for |
|---|---|---|
| Quick Check | 1 hour | Verifying your data pipeline works, getting a rough baseline |
| Baseline Search (Recommended) | 6 hours | Most use cases — good balance of exploration and cost |
| Thorough Search | 24 hours | Large or complex datasets where marginal accuracy gains matter |
| Custom | Set your own | When you know your compute budget or have specific time constraints |
Why did we build it?
- Eliminate manual tuning: No more creating one model at a time, tweaking parameters, and manually comparing results.
- Weeks of work in hours: Auto Tune explores configurations in parallel — work that would take weeks of manual experimentation — and completes a typical search in 6 hours.
- Cost-predictable: Search cost is bounded by time budget × hardware rate. For example, a 6-hour Baseline Search on Grossular-4 ($6.87/hr) costs at most ~$41.
- Learn from past runs: Compatible Prior Runs mode seeds new searches with hyperparameters from successful prior Auto Tune runs in your organization, so you benefit from your team’s history. The current run’s best hyperparameters are contributed back for future use.
How is it used? By whom?
- Simulation engineers select Auto Tune when creating a new model in AI Physics. Choose an architecture, pick a search duration, select GPU hardware, and click Start. Auto Tune runs autonomously — when complete, review the R² score in the Versions table to confirm quality before deploying for inference.
- Teams with prior training history can enable Compatible Prior Runs in Advanced Settings to seed hyperparameters from prior successful runs on similar datasets, narrowing the search space and converging faster.
- Power users can expand Technical Details during a search to view the Efficiency Frontier (accuracy vs. training cost) and the Promotion Ladder (rung-based advancement system) for deeper insight into the search process.
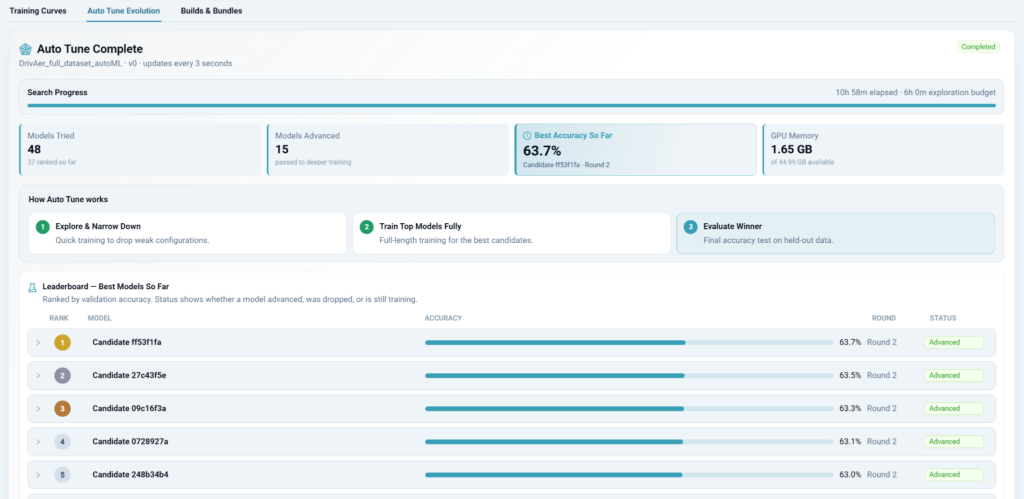
Monitor Auto Tune progress in real time — see models tried, models advanced, and current best accuracy on the Auto Tune Evolution tab.
Getting Started
- Navigate to AI Physics > Models and click + New Model.
- Select Auto Tune as your configuration method.
- Choose your model architecture (DoMINO, TwoStreamTransformer, GeoTransolver, or MeshGraphNet).
- Set your search duration — Baseline Search (6 hours) is recommended for most use cases.
- Select GPU hardware and click Start Auto Tune.
When complete, check the R² score in the Versions table. A value close to 1.0 means the model is ready to deploy for inference. If R² is low or negative, try increasing search duration, adding more training data, or switching to a different architecture.